

When I'm not sure what to write about, I check Mistral's socials, and voilà. Depressing.
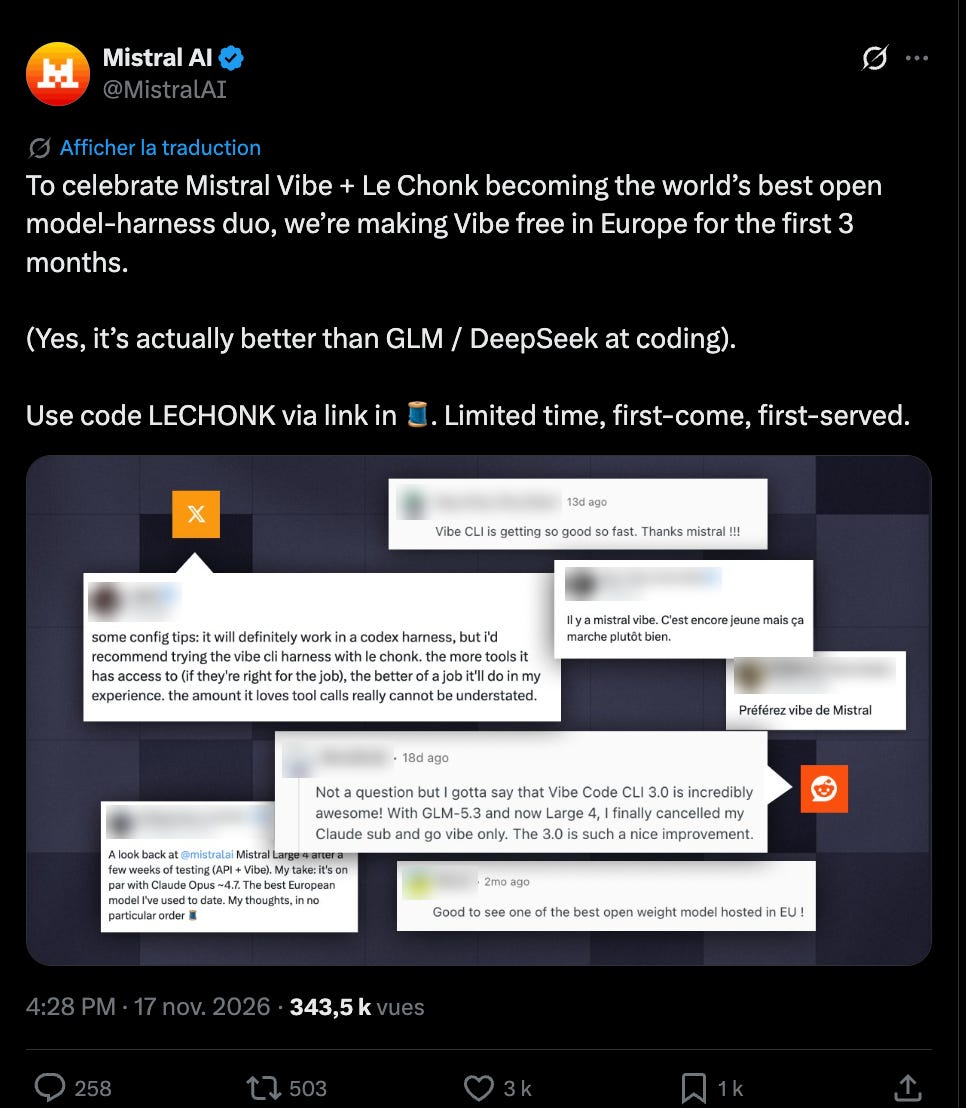
On November 17th, 2026, Mistral posted this on X: "To celebrate Mistral Vibe + Le Chonk becoming the world's best open model-harness duo, we're making Vibe free in Europe for the first 3 months. (Yes, it's actually better than GLM / DeepSeek at coding)."[1] Le Chonk is Mistral Large 4, and Vibe is Mistral's coding agent.
Three free months of a European coding agent is a good offer, and I'd take it. The sentence in front of the offer is the problem. The pair is not the world's best open duo, the index Mistral's own release page cites has never said so, and its latest version had been public for three days.
What did Mistral attach as evidence?
A picture of seven social media posts.[1] No number, no chart, no link to a benchmark.
Given how Mistral's benchmark numbers have behaved in the last couple of weeks (a preview score with no agent named, a headline run AA deleted and then restored, an effort level its agent offered and its API refused), maybe leaving the numbers out was the prudent call. Still, "world's best" is a ranking, and a ranking needs a board.
So, the collage. One fan writes that Vibe "is getting so good so fast". Another, in French, says it is "still young, but it works rather well". The strongest calls Large 4 "on par with Claude Opus ~4.7", which is a compliment, not a ranking. A comment stamped two months old, so older than Large 4's weights, is glad to see "one of the best open weight model hosted in EU". My favorite is the Reddit one: "With GLM-5.3 and now Large 4, I finally cancelled my Claude sub and go vibe only." Mistral's exhibit for Large 4 beating GLM is a user who names GLM-5.3 first.
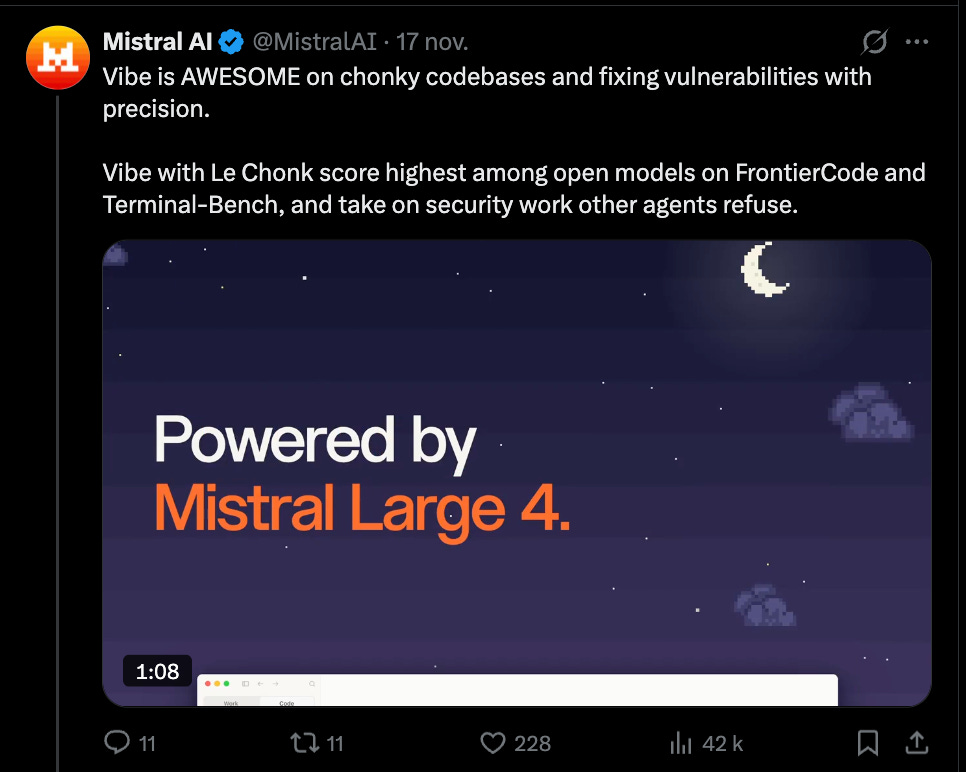
The thread does name two benchmarks: Vibe with Le Chonk "score highest among open models on FrontierCode and Terminal-Bench".[1] It names them over a product video, with no number and no source. Fine. I looked them up.
What does the Artificial Analysis Coding Agent Index say?
Artificial Analysis (AA) publishes the Coding Agent Index, which gives a model inside a coding agent a score out of 100, the mean of three benchmarks, two of them FrontierCode and Terminal-Bench. It announced version 2.1 on November 14th.[2] Here are the open-weight models in AA's default rows, each in the agent AA pairs it with.[3]
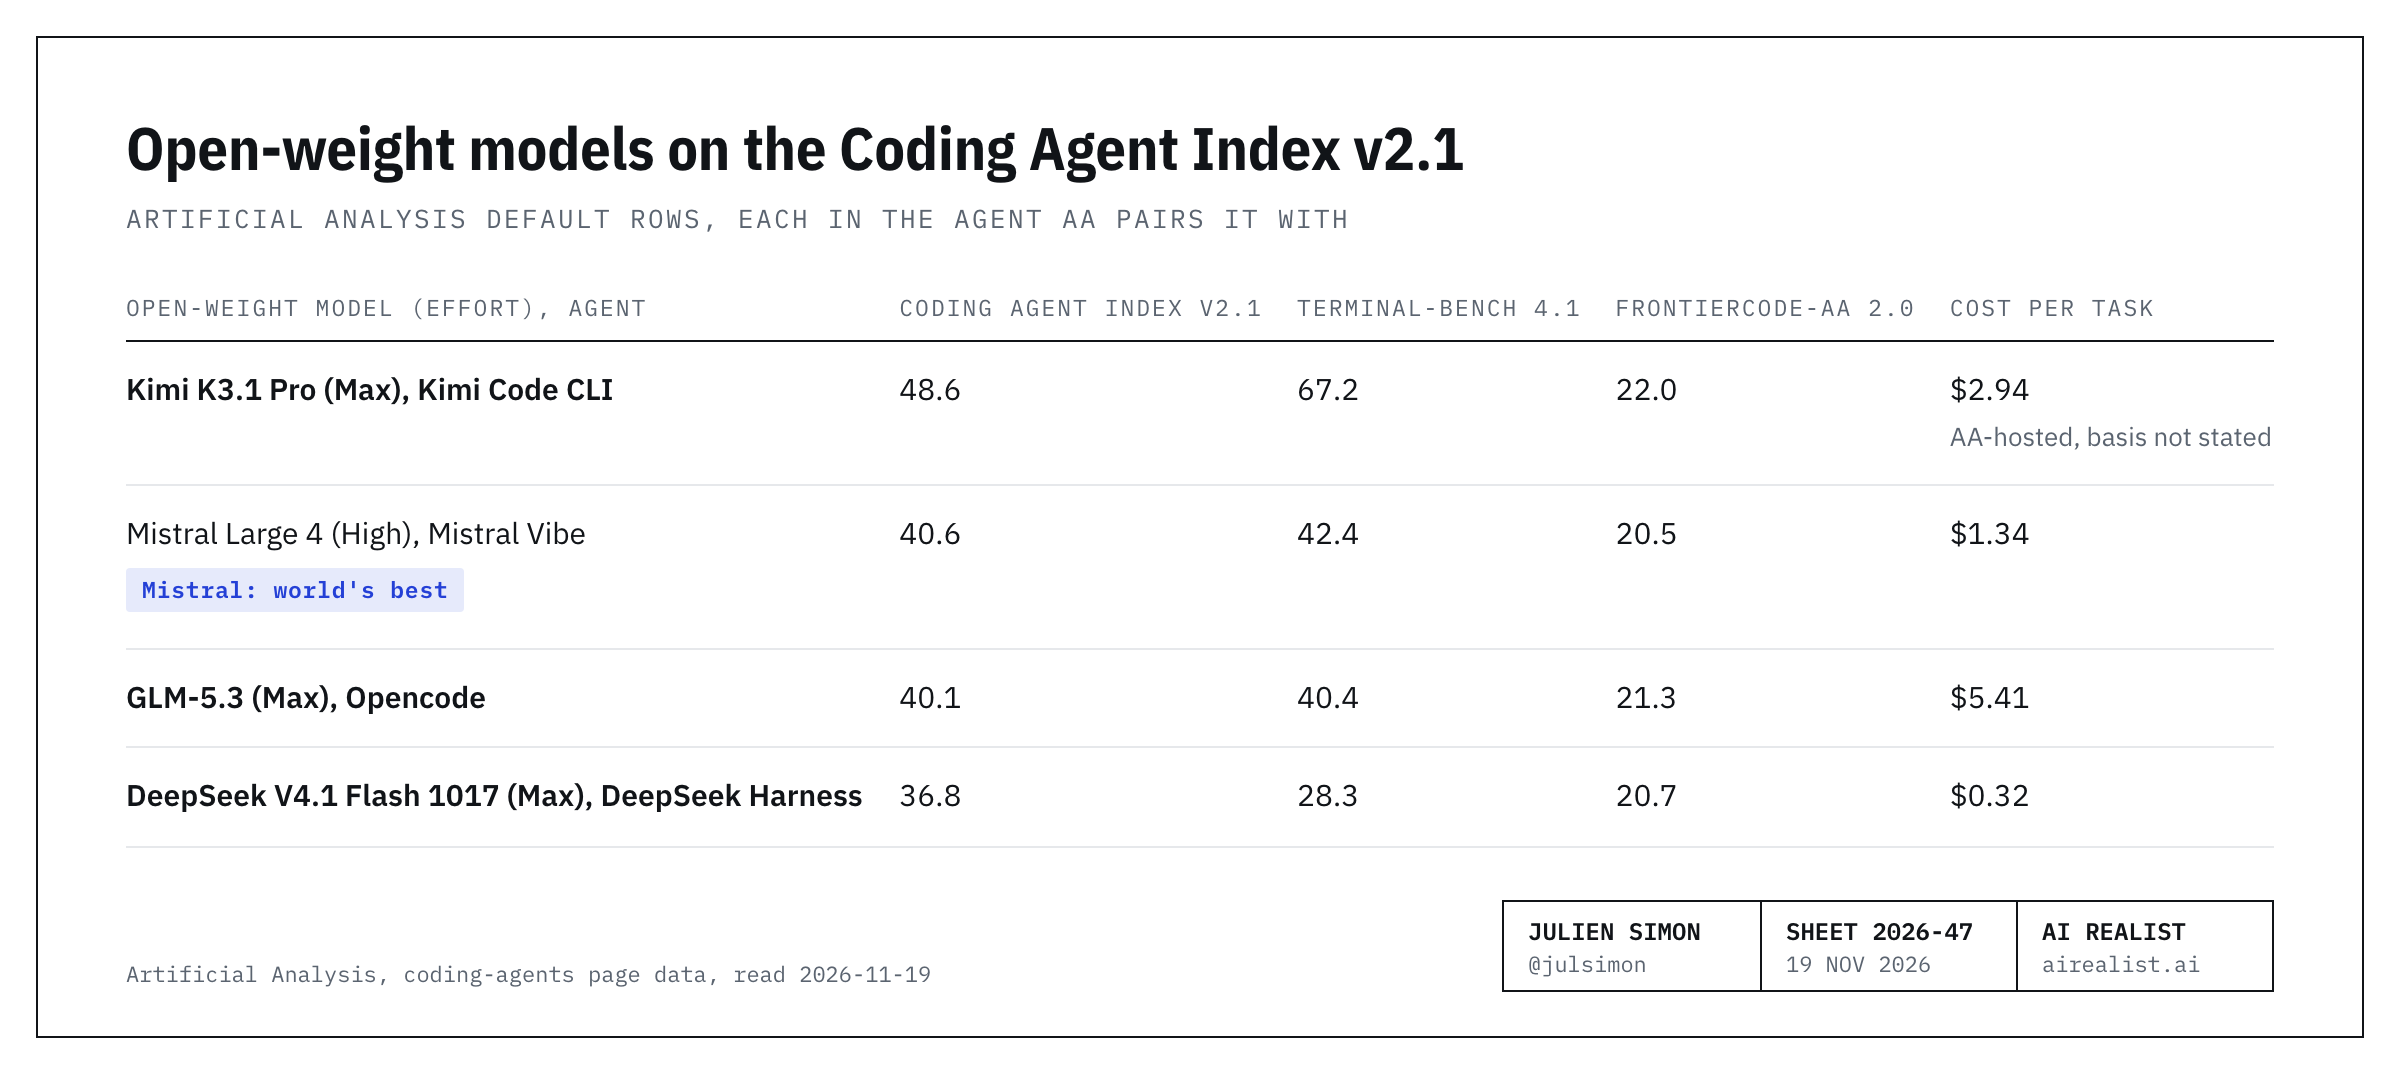
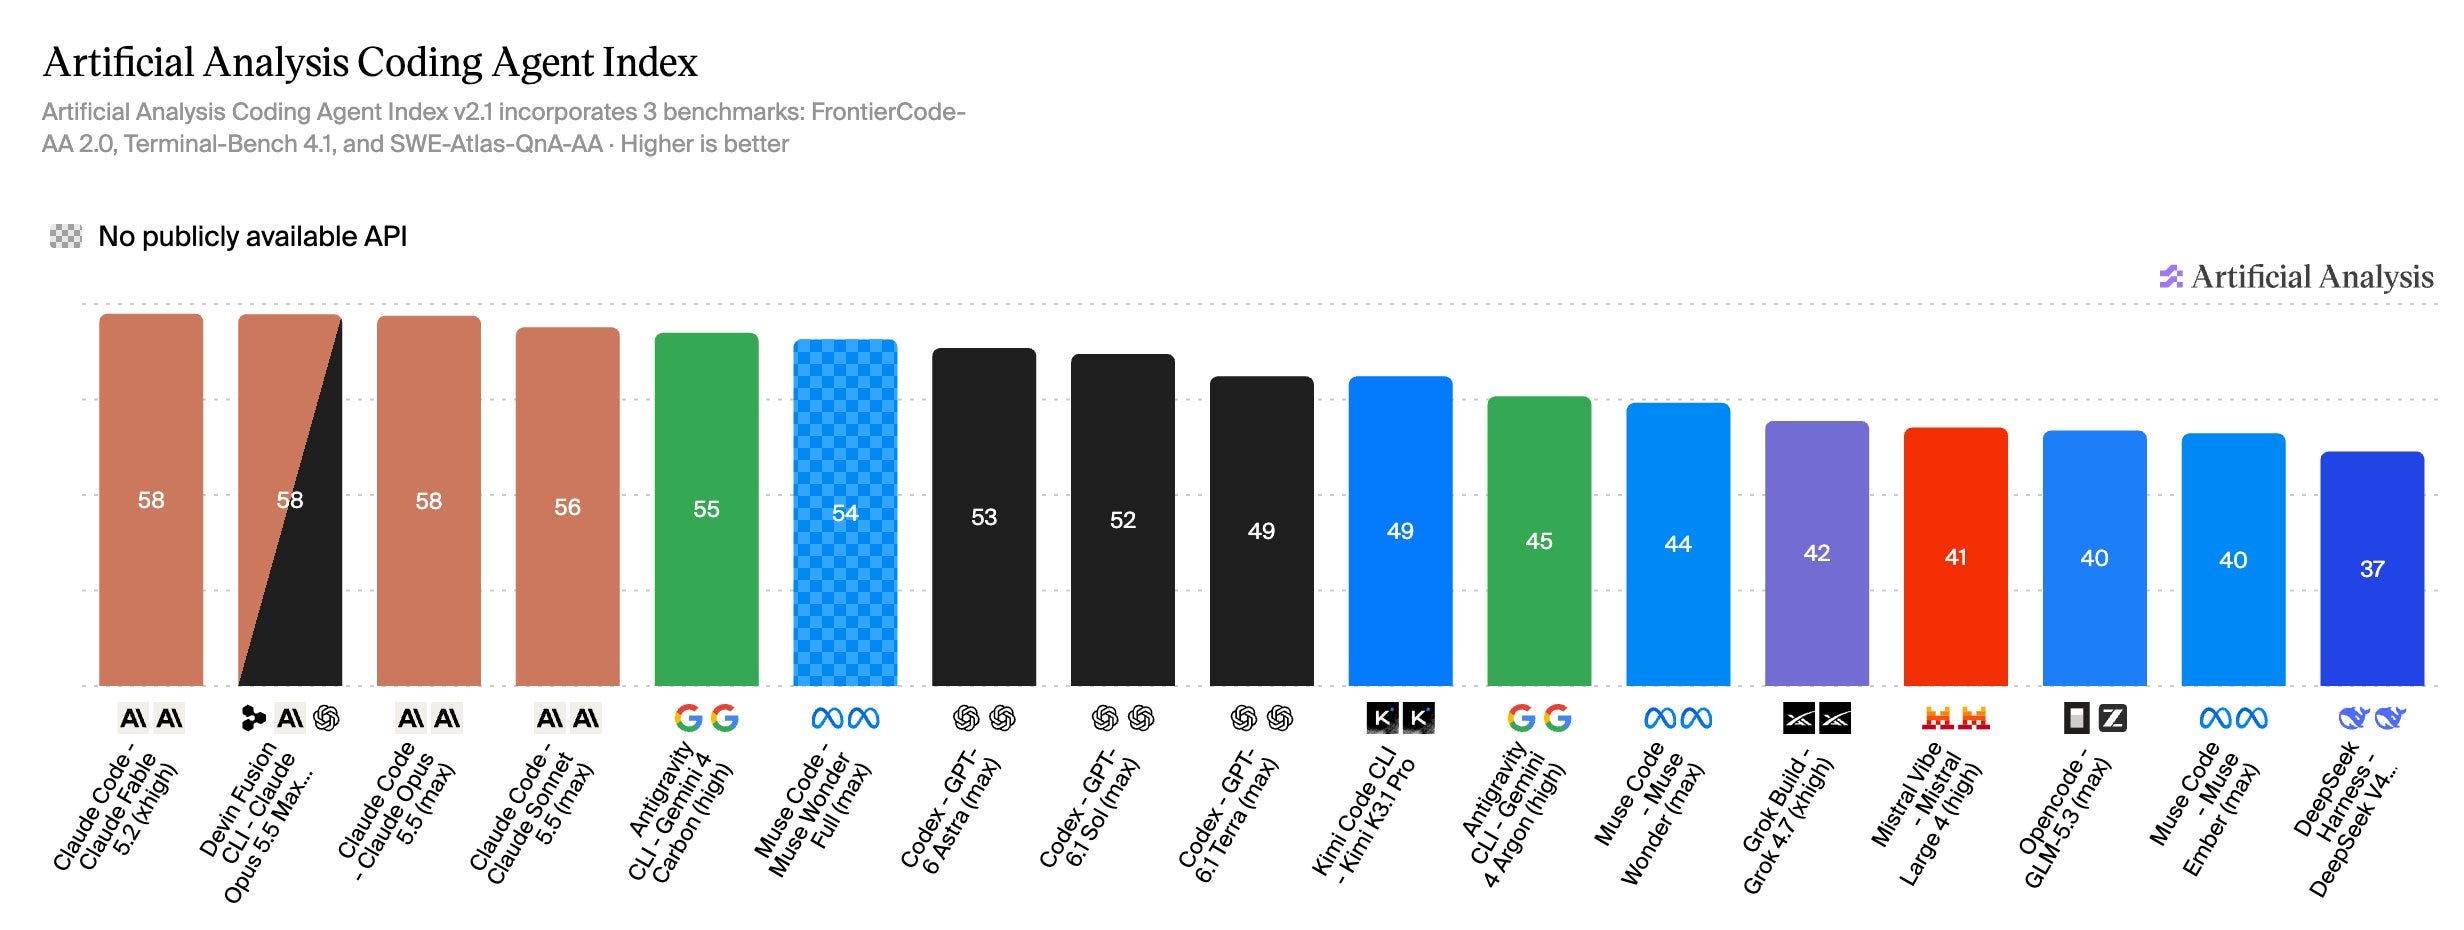
"Highest among open models on Terminal-Bench" was true on the previous version of AA's index, before Kimi K3.1 Pro had a row.[4] On the current one, it is 25 points behind Kimi. The official Terminal-Bench leaderboard has no Vibe entry: its one Large 4 row runs in Claude Code, at 27.6, and doesn't say which Large 4 it is.[5]
"Highest on FrontierCode" was true once. Mistral's release page cites Cognition's own chart, where Large 4 led the open models at 19.7. Cognition's data has moved since: it added new models, and on November 11th it rescored every result. By November 12th, four open models sat above Large 4, whose score has not moved: Thinking Machines' new Inkling 2 Small, three points clear, then DeepSeek, GLM-5.3, and Kimi K3.1 Pro, all within a task or two of it, out of 132. AA's run agrees: last of its four, again within a task or two. Call it a four-way tie for second place. That is not "highest".[3][5]
They're cherry-picking benchmarks, again. Three weeks ago, Mistral's release page quoted the AA Coding Agent Index by name, with GLM-5.3 as "the leading open-weight model" and Large 4 level with it.[4] Its summary line then was "taking the lead on FrontierCode and Terminal-Bench while matching the best open-weight models" on that index. Now, with Kimi 8 points ahead, the thread repeats the first half, after both boards had moved, and drops the index. And the FrontierCode chart on its own page still compares against the older Kimi, when Cognition and AA both list the new one.
Is Kimi open? Its weights are on Hugging Face, AA's data lists AA itself as the provider for its run, and Kimi Code CLI is under the MIT license.[6] The Kimi license has a clause for model-hosting businesses in a group with more than $20 million in revenue. Mistral's has the same clause with no revenue floor, as I wrote in "Mistral Large 4 Weights: The Score Comes With the Harness". AA's own Openness Index scores Large 4 at 39 out of 100 and Kimi at 33, a scale that shuts nobody out, and it puts DeepSeek above both at 44.[6] I can't find a definition of "open" that keeps Large 4 and drops Kimi. If Kimi K3.1 Pro with Kimi Code CLI doesn't qualify as open, Mistral should explain why.
Mistral found a simpler answer: the post names GLM and DeepSeek and leaves Kimi out.
Is Vibe with Large 4 better than GLM-5.3 and DeepSeek?
Against DeepSeek, yes, by almost four points. Against GLM-5.3, on paper, by half a point: 40.6 against 40.1. It comes from Terminal-Bench, where it is 84 passing attempts against 80, out of 198. Four attempts, about one task.[3]
Mistral's own release page has a word for a gap that size. On version 2.0 of the index, Large 4 sat 0.6 points behind GLM-5.3, and the page, unchanged since November 5th, calls that "effectively tied". The same page calls 0.4 points ahead on FrontierCode a "lead".[4] So: six-tenths behind is a tie, four-tenths ahead is a lead, and half a point ahead is "actually better". I'm starting to see how the unit works.
The post Mistral could have written
Here is the post, free of charge: "Vibe with Le Chonk ties GLM-5.3 at a quarter of the cost per task: $1.34 against $5.41." Every number in it is on AA's page today.[3] If you pay for tokens, that pitch works on you, and it needs no adjective. (DeepSeek is cheaper still, and four points behind.)
Why overclaim and look bad? Large 4 looks good as it is. Honesty wins.
Needless to say, I'll check their socials again next week.
Notes
[1] Mistral AI on X, 2026-11-17 15:28 UTC, text and image read on 2026-11-19: the quoted text, followed by "Use code LECHONK via link in 🧵. Limited time, first-come, first-served." The attached image is a collage of seven posts and comments, with X and Reddit logos and no chart; one comment is stamped "2mo ago". The French comment reads "Il y a mistral vibe. C'est encore jeune mais ça marche plutôt bien."; the translation is mine. The Reddit comment in full: "Not a question but I gotta say that Vibe Code CLI 3.0 is incredibly awesome! With GLM-5.3 and now Large 4, I finally cancelled my Claude sub and go vibe only. The 3.0 is such a nice improvement." Another post in the collage: "My take: it's on par with Claude Opus ~4.7. The best European model I've used to date." Mistral's post The thread, read in a browser the same day, has three more posts by Mistral. The second: "Vibe with Le Chonk score highest among open models on FrontierCode and Terminal-Bench, and take on security work other agents refuse.", over a video, with no figure and no link. second post of the thread The fourth carries the offer link and "Terms apply." Second document: Sovereign Magazine's report of the offer and of the thread's claims. Sovereign Magazine The three items in the parenthesis are from my two earlier pieces: the preview's 28 (the fifth note of my November 1st piece), the run removed and restored (the update at the top of my November 11th piece), and the effort levels (the seventh note of my November 11th piece).
[2] Artificial Analysis on X, 2026-11-14 00:04 UTC, read 2026-11-19: "Announcing Artificial Analysis Coding Agent Index v2.1, upgrading FrontierCode and Terminal-Bench." Its chart shows "Kimi Code CLI - Kimi K3.1 Pro" at 49 and "Mistral Vibe - Mistral Large 4 (high)" at 41, and its cost chart labels the Kimi point "Kimi Code CLI - Kimi K3.1 Pro (Self-hosted)". The post's text does not name Kimi or Mistral. AA's announcement Second document: the Internet Archive capture of 2026-11-14 01:25 UTC of AA's page, with data stamped 2026-11-13 23:28 UTC, carrying both rows with the scores in note 3. Mistral's post (note 1) came 3 days, 15 hours and 24 minutes after this one, by the two posts' times.
[3] Artificial Analysis, Coding Agent Index page, data embedded in the page, read raw on 2026-11-19, data stamped 2026-11-19 14:52 UTC. Index score, then FrontierCode-AA 2.0, SWE-Atlas-QnA-AA and Terminal-Bench 4.1, then mean cost per task: Kimi Code CLI with Kimi K3.1 Pro (max) 48.64, 22.02, 56.72, 67.17, $2.94; Mistral Vibe with Mistral Large 4 (High) 40.59, 20.47, 58.87, 42.42, $1.34; Opencode with GLM-5.3 (Max) 40.12, 21.35, 58.60, 40.40, $5.41; DeepSeek Harness with DeepSeek V4.1 Flash 1017 (Max) 36.83, 20.66, 61.56, 28.28, $0.32. High is the top effort AA lists for Large 4. The index is the mean of the three benchmarks. Terminal-Bench 4.1 has 66 tasks, three attempts each; passing attempts less the attempts AA flags for reward hacking: 133 for Kimi, 84 for Vibe with Large 4, 80 for Opencode with GLM-5.3, each over 198 (AA logs 197 attempts for the Vibe row and scores the missing one as a fail). The table lists AA's default rows whose model has published weights. Left out: Beam 1.0 (15.5) and Step 5 Preview (35.8, run in Claude Code), both with published weights and neither a default row; Muse Ember (39.7), which has no weights in Meta's Hugging Face organization; Qwen3.8 Max (32.7, not a default row), which has no published weights. AA's page data names AA itself as the provider of the Kimi run, and its methodology does not say how it prices a run it hosts, so the Kimi cost is not compared here. Under Terminal-Bench 4.1, an attempt the new graders cannot grade keeps its 4.0 score. AA's FrontierCode is its own run of Cognition's 132 tasks. AA Coding Agent Index AA methodology Second document: the Internet Archive capture of 2026-11-18 01:02 UTC, with the same four rows and scores. Author's calculation from AA's page: 48.64 − 40.59 = 8.05. Author's calculation from AA's page: 67.17 − 42.42 = 24.75. Author's calculation from AA's page: 40.59 − 36.83 = 3.76. Author's calculation from AA's page: 40.59 − 40.12 = 0.47. Author's calculation from AA's page: 22.02 − 20.47 = 1.55. Author's calculation from AA's page: 1.34 ÷ 5.41 ≈ 0.25.
[4] Mistral, "Mistral Large 4 (Le Chonk) is now open weight", raw page read 2026-11-19: "On the Artificial Analysis Coding Agent Index, Mistral Large 4 scores 48%, effectively tied with the leading open-weight model, GLM-5.3"; "taking the lead on FrontierCode and Terminal-Bench"; "On Cognition's private FrontierCode 2.0 benchmark", "Mistral Large 4 leads with a score of 19.7%", against 19.3% for DeepSeek V4.1 Flash on the same chart, which lists Kimi K3 and not Kimi K3.1 Pro. The page's metadata gives "dateModified" 2026-11-05 16:40 UTC. Mistral release post Second document: the Internet Archive capture of 2026-11-13 01:04 UTC of AA's page, the last one I read on version 2.0: Opencode with GLM-5.3 (Max) 48.92, Mistral Vibe with Mistral Large 4 (High) 48.28. Author's calculation from that capture: 48.92 − 48.28 = 0.64. Author's calculation from Mistral's chart: 19.7 − 19.3 = 0.4. On version 2.0, AA's own launch post of 2026-10-29 said Large 4 in Vibe "ranks second of the current open weights models"; from 2026-11-06 to 2026-11-11, AA's page showed 35.4 for it (see the update at the top of my November 11th piece). Kimi K3.1 Pro has no row on version 2.0. On Terminal-Bench 4.0 in the same capture, Vibe with Large 4 reads 41.4 and Opencode with GLM-5.3 39.9, the highest of the open-weight rows. The captures of AA's page read for this piece and for my November 11th piece, from 2026-11-01 to 2026-11-13, all show GLM-5.3 ahead of Vibe with Large 4. AA's October 29th post
[5] Cognition, FrontierCode 2.0, the data file behind its leaderboard page, read 2026-11-19: 132 tasks; best score per model on "new_score", the score Cognition's chart shows (Mistral's 19.7 is Large 4's new_score): Inkling 2 Small 22.57, DeepSeek V4.1 Flash 1017 20.19, GLM 5.3 20.15, Kimi K3.1 Pro 19.89, Mistral Large 4 19.65. On the file's "correct" column the same five read 25.51, 22.98, 22.73, 21.97 and 21.97: Kimi K3.1 Pro and Large 4 tie. Cognition runs Large 4 in Vibe and the other four in Devin CLI. Cognition FrontierCode Inkling 2 Small: thinkingmachines/Inkling-2-Small on Hugging Face, Apache 2.0, public, created 2026-11-04 (Hugging Face API, read 2026-11-19); it has no row on AA's index. Inkling 2 Small repository Internet Archive captures of Cognition's file: 2026-10-30, Large 4 19.65, DeepSeek V4.1 Flash 19.30, GLM 5.3 17.81, Kimi K3 17.74; 2026-11-06, Large 4 19.65, Kimi K3.1 Pro 19.64, DeepSeek V4.1 Flash 19.30, no Inkling 2 Small; 2026-11-12 22:19 UTC and 2026-11-19 00:07 UTC, the five values read today. The post falls between those last two captures, which agree. In the two earlier captures the only models above Large 4 have no published weights. Cognition's page changelog, read 2026-11-19: "Nov 5, 2026 Models Added Kimi K3.1 Pro."; "Nov 9, 2026 Models Added GPT-6.2 Astra and GPT-6.2 Sol. Added Fable 5.2 and Inkling 2 Small."; "Nov 11, 2026 Reporting Updated the cheating scanner to remove false positives: it now combines rule-based checks with a filtering judge. All results are rescored." Large 4 reads 19.65 before and after the rescoring. Author's calculation from Cognition's file: 100 ÷ 132 ≈ 0.76. Author's calculation from Cognition's file: 22.57 − 19.65 = 2.92. Author's calculation from Cognition's file: (22.98 − 21.97) ÷ 0.76 ≈ 1.3. Author's calculation from AA's page: (22.02 − 20.47) ÷ 0.76 ≈ 2.0. Terminal-Bench 4.1 leaderboard, read 2026-11-19: no row for Mistral Vibe; one Mistral Large 4 row (max), in Claude Code, 27.6% plus or minus 3.9; its release-date column reads October 6th, 2026, the day the preview launched, its link points to the API name mistral-large-4-0, and the page does not say which checkpoint ran. In the same agent, Kimi K3.1 Pro (max) reads 59.7%. Terminal-Bench leaderboard
[6] Hugging Face, moonshotai/Kimi-K3.1-Pro, read through the Hugging Face API on 2026-11-19: public, not gated, created 2026-11-02, 96 weight files. Its license file, "Kimi K3.1-Pro License", read the same day: an MIT-style grant; a licensee that "operates a Model as a Service business" with aggregate revenue above "20 million US dollars" over twelve months "must enter into a separate agreement with Moonshot AI"; a second clause requires large products to display the model's name. Kimi K3.1 Pro repository Kimi Code CLI: MIT license, read through the GitHub API on 2026-11-19. Kimi Code CLI repository Mistral Vibe is under Apache 2.0. Mistral Vibe repository Mistral's own statement of its condition, on its release page, read 2026-11-19: "businesses that operate a Model-as-a-Service offering must obtain a separate commercial license from Mistral before using the model commercially." Mistral release post "Self-hosted" is AA's label (note 2), and AA's page data names AA as the provider of that run (note 3). Artificial Analysis Openness Index, read 2026-11-19, "a 0 to 100 normalized scale (higher is more open)": Mistral Large 4 39, Kimi K3.1 Pro 33, GLM-5.3 33, DeepSeek V4.1 Flash 44. AA Openness Index
[7] Mistral, careers page, read 2026-11-19: "900+ employees". Mistral careers page